How Esy works
Esy executes AI workflows that produce artifacts. A workflow defines the inputs it accepts, the steps it runs, the models and tools those steps call, and the checks its output must pass. Executing a workflow creates a run. During the run Esy executes each step in order, records every provider call and its cost, applies automated and human checks, and stores the output as an artifact.
Execution overview
Every request follows the same path. The rest of this page explains each part, and links to the reference page for it.

Workspaces and projects
These are organizational, not execution concepts. Nothing about them changes how a workflow runs — they determine who can see a run and where its spend is counted.
| Object | What it is | Endpoint |
|---|---|---|
| Workspace | The billing and membership boundary. Every run, artifact, and budget belongs to one.kind is organization or personal, and that set is enforced by the database. Your personal workspace is created for you at signup. | /v1/workspaces |
| Project | An optional grouping inside a workspace, so runs and costs roll up somewhere meaningful.kind defaults to general; brand is the other value in active use. Unlike workspace kind, it is a free-form string. | …/projects |
kind is organization. These docs say workspace throughout.Workflows
A workflow is a versioned definition, not a prompt. It declares what it accepts, what it runs, and what it produces. The persisted type is WorkflowTemplate, and these are its fields:
| Field | Type | Required | Description |
|---|---|---|---|
intakeSchema | object | required | The inputs this workflow accepts — field names, types, enums, defaults, and which are required. |
runtimeSteps | array | required | The ordered list of steps to execute. Note the field name: it is runtimeSteps, not steps. |
gates | array | optional | Declared checks. An entry with type "approval" or "hitl" makes the run stop for a human decision. |
providers | object | required | Binds each step role (imageGenerator, textGate, classifier) to a concrete registry model id. |
budgetPolicy | object | optional | Per-run ceiling for this workflow, e.g. perRunCapUsd. |
artifactSchema | object | required | The declared output: artifactClass, artifactType, file types, and expected metadata keys. |
version | string | required | The template version a run pins. Versions are immutable; a live pointer moves between them. |
visibility | enum | required | draft (unlisted), internal (operators can run it), or public (listed in the public catalog). |
Here is a real one — generate-coloring-page, trimmed to the fields above. Prompt bodies come back as the literal string redacted: the catalog publishes the shape of a pipeline, not its wording.
{
  "id": "generate-coloring-page",
  "artifactClass": "visual",
  "schemaVersion": "workflow-schema-v1",
  "version": "2026.09.16",
  "visibility": "public",
  "intakeSchema": {
    "fields": [
      { "name": "prompt", "type": "string", "required": true },
      { "name": "aspectRatio", "type": "enum", "required": true, "default": "3:4",
        "options": ["1:1", "3:4", "4:3", "3:2", "2:3", "16:9", "9:16"] },
      { "name": "size", "type": "string", "required": false, "default": "",
        "description": "Exact WIDTHxHEIGHT. Empty means aspectRatio decides." },
      { "name": "detail", "type": "enum", "required": false, "default": "print",
        "options": ["print", "app"] }
    ]
  },
  "runtimeSteps": [
    { "id": "step-1", "name": "Render line art", "kind": "image",
      "role": "imageGenerator", "promptTemplate": "redacted" },
    { "id": "step-2", "name": "Post-process line art", "kind": "tool",
      "tool": "esy/line-art-print", "inputPath": "step-1.url" },
    { "id": "step-3", "name": "Audit line art", "kind": "tool",
      "tool": "esy/line-art-audit", "inputPath": "step-2.url" },
    { "id": "step-3b", "name": "Text gate", "kind": "llm",
      "role": "textGate", "requireTrue": "pass" },
    { "id": "step-4", "name": "Classify", "kind": "llm", "role": "classifier" }
  ],
  "gates": [
    { "id": "gate-render", "name": "Provider execution", "type": "quality" },
    { "id": "gate-line-art", "name": "Line-art audit", "type": "quality" },
    { "id": "gate-text", "name": "OCR text gate", "type": "quality" }
  ],
  "providers": { "imageGenerator": "openai/gpt-image-2.5-flare-2026-09-08" },
  "budgetPolicy": { "perRunCapUsd": 0.30 },
  "artifactSchema": {
    "artifactClass": "visual",
    "artifactType": "coloring-page",
    "files": ["image/png"]
  }
}
A step names a role rather than a model, and providers binds that role to a registry id. Swapping the image model is a change to one binding, not to any step. Workflows covers the full contract.
Runs
A run is one execution of one workflow version. It records per-step timing, the provider and model each step used, the cost of each call, and the artifact it produced. Create one by posting a templateId and an intake matching that workflow’s intakeSchema:
curl -X POST https://api.esy.com/v1/runs \
  -H "Authorization: Bearer $ESY_API_KEY" \
  -H "content-type: application/json" \
  -d '{
    "templateId": "generate-coloring-page",
    "intake": {
      "prompt": "a cartoon lion sitting in tall grass",
      "aspectRatio": "3:4",
      "quality": "medium",
      "detail": "print",
      "categories": "animals-coloring"
    }
}'{
"id": "run-7c41e9a2",
"status": "pending",
"templateId": "generate-coloring-page",
"templateName": "Generate Coloring Page",
"currentStepIndex": 0,
"workflowVersion": "2026.09.16",
"specVersionHash": "sha256:eb3ced0c91a625e7ad47beaa28f5ff7b6db933ca5f6cac78fb93c1b030852fdb",
"createdVia": "api_key",
"queuedAt": "2026-09-16T14:22:08.317Z"
}The response returns immediately with status: "pending". Execution is asynchronous — poll GET /v1/runs/{id} or subscribe to run events over SSE.
Run statuses
There are ten status values. Six are terminal for the executor; four mean the run is still moving. Break a polling loop on any terminal status, not on completed alone.
| Status | Meaning | Terminal |
|---|---|---|
| pending | Created, not yet queued. | No |
| planned | A child run of a Generation Order, created but not yet dispatched. | No |
| queued | Waiting for an executor. | No |
| running | Executing steps. | No |
| completed | All steps finished and any human gate approved. | Yes |
| review | Steps finished; a human decision is required before the run resolves. | Yes * |
| failed | A step raised, or an automated gate rejected the output with no fallback left. | Yes |
| cancelled | Cancelled through the API. | Yes |
| rejected | A reviewer rejected the output. | Yes |
| changes_requested | A reviewer asked for changes. Revising spawns a new run. | Yes |
review, which is why it belongs in your polling loop’s exit set. It is not final: a reviewer resolves it into completed, rejected, or changes_requested through POST /v1/queue/{runId}/decide. A run only enters review if its workflow declares an approval or hitl gate — otherwise running goes straight to completed.Runs and steps documents per-step telemetry and recovery.
Steps and gates
A step performs work: it calls a model, runs a tool, or invokes another workflow. A gate does not perform work — it evaluates output that already exists and determines whether execution continues. The two are declared in different places and fail in different ways.
Step kinds
Five kinds are dispatched by the engine:
| Kind | What it does |
|---|---|
llm | Calls a language model. Can declare a jsonSchema for structured output, and repeat to fan out over chunks. |
image | Calls an image model. Resolves its model from the binding, or from an intake field when the template declares one. |
tool | Runs a registered Esy tool — image post-processing, audits, format conversion. Most tools are local and cost nothing. |
subWorkflow | Runs another workflow as a child run, and rolls its cost up into this one. |
agent | Runs an agent step with tool access. |
kind is anything else — including code and qa — falls through to a pass-through branch that records the step for provenance and makes no provider call. If you declare a code step expecting it to run code, it will not; it becomes a no-op marker in the run record.Automated gates
An automated check is declared on the step that produces the verdict, using requireTrue. It names a field of that step’s parsed JSON output which must be truthy for execution to continue:
{
  "id": "step-3b",
  "name": "Text gate",
  "kind": "llm",
  "role": "textGate",
  "requireTrue": "pass",
  "failMessage": "Lettering does not match the declared text contract",
  "jsonSchema": {
    "type": "object",
    "properties": {
      "pass": { "type": "boolean" },
      "readText": { "type": "string" }
    }
  }
}
If the field is missing, unparseable, or falsy, the step raises a verdict error. Before failing the run, the engine tries the next available fallback mechanism for that output — for image work, an alternative background-removal approach on the same render. If no fallback remains, the run fails and records structured evidence, including the URL of the output that was rejected:
{
  "id": "run-7c41e9a2",
  "status": "failed",
  "errorCode": "StepVerdictError",
  "error": "step 'step-3b' verdict false: lettering does not match",
  "failureDetails": {
    "kind": "gate_rejected",
    "failures": ["textContract"],
    "stepId": "step-3b",
    "rejectedUrl": "https://images.esy.com/artifacts/coloring-page/run-7c41e9a2/raw.webp"
  }
}
Human gates
A human check is declared in the template’s gates array with type: "approval" or type: "hitl". When a workflow declares one, the run stops at review after its steps finish and waits for a decision. A gate entry with type: "quality" is automated and never parks a run.
unlocks field naming a step id. It documents intent in the published contract; the engine does not read it to schedule work. Execution order is the order of runtimeSteps, and what actually blocks progress is a requireTrue verdict or a human gate. Do not build a client that expects unlocks to control sequencing.
Gates and review covers the review queue and typed holds.
Artifacts
An artifact is the stored output of a run, plus the record of how it was produced. It has its own id and endpoint, and outlives the run.
{
  "id": "artifact-0dc32dbb",
  "runId": "run-7c41e9a2",
  "templateId": "generate-coloring-page",
  "status": "ready",
  "artifactClass": "visual",
  "artifactType": "coloring-page",
  "version": 1,
  "specVersionHash": "sha256:eb3ced0c...",
  "content": {
    "type": "image",
    "url": "https://images.esy.com/artifacts/coloring-page/artifact-0dc32dbb/processed.webp",
    "storageKey": "artifacts/coloring-page/artifact-0dc32dbb/processed.webp",
    "model": "openai/gpt-image-2.5-flare-2026-09-08"
  },
  "qa": {
    "status": "pass",
    "checks": [
      { "id": "line-art-audit", "status": "pass", "detail": "stroke 1.8pt" },
      { "id": "text-gate", "status": "pass", "detail": "" }
    ]
  },
  "metadata": { "aspectRatio": "3:4", "detail": "print" }
}
Three fields carry everything Esy preserves. content holds the output itself — file URL, storage key, and the model that produced it. qa holds each check that ran and its verdict. metadata holds the keys the workflow’s artifactSchema declared. Alongside them, specVersionHash pins the exact workflow version the run executed, so an artifact can be traced to the definition that made it.
provenance field on an artifact. Provenance data — the model used, the mechanism chosen, per-check verdicts — is written by the engine into the content and qa JSON. Read it from there, and do not expect a fixed schema across artifact types.Files are stored under artifacts/{artifactType}/{artifactId}/. Artifacts has the full storage layout.
Inputs and model selection
An intakeSchema field asks for a result, not for the technique used to get it. A clip-art workflow accepts backgroundRemovalEnabled: true; it does not ask which removal algorithm to apply. The engine resolves that from the bound model.
Concretely: each entry in the model registry carries capability flags, one of which is supports_native_transparency. If the bound image model declares it, the engine renders transparency directly and skips the removal step. If it does not, the engine renders normally and runs a removal tool afterwards. Either way it records which path it took in the step output as transparencyMechanism, one of:
| Value | What ran |
|---|---|
native | The image model produced transparency directly; the removal step was skipped. |
chroma-key | Rendered on a keyable background, then keyed out. |
difference-matte | Rendered twice against different backgrounds and matted by difference. |
post-process | A background-removal model ran on the finished render. |
The practical consequence is compatibility: because a saved intake never names a mechanism, it stays valid when a model gains a capability or a binding changes. Only the recorded provenance differs between runs. Quality checks evaluate the resulting image, so a new mechanism does not require rewriting them.
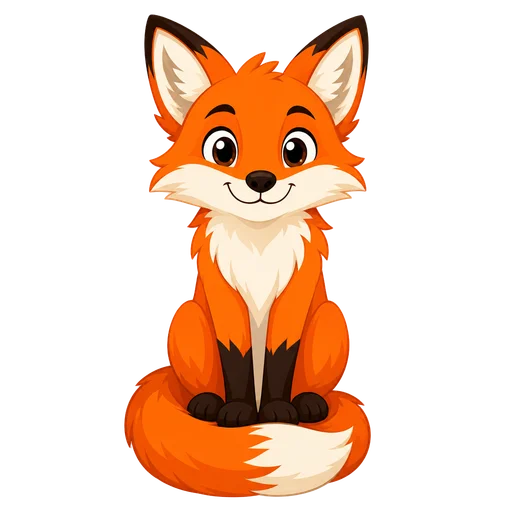
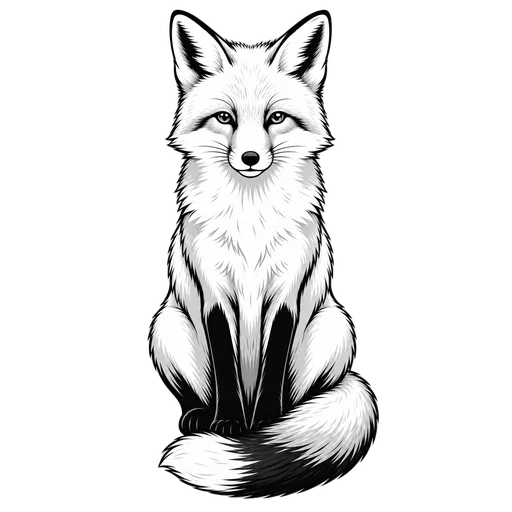
Two production renders of the same subject under different intake values. The style is an intake field; the model behind it is a binding. Intake documents schema field types.
Costs and budgets
Cost is recorded per provider call, not per run. Every call writes one row to the provider cost ledger, carrying the provider, model, quantity, unit price, and the run and step it belongs to. A single step can produce several rows — a step that fans out over chunks writes one per call.
Each row moves through three states:
Budgets
A budget attaches to a workspace, a project, or a workflow, over a period of total, daily, weekly, or monthly. It is evaluated before a run starts, against the run’s estimate — not against actual spend afterwards. Its enforcementMode decides what happens when the estimate would push spend past the limit:
| Mode | Behaviour |
|---|---|
hard_stop | Refuses the run when spend plus estimate exceeds the limit. |
allow_overage | Permits spend past the limit up to a declared overage amount, then refuses. |
allow_one_more | Permits one run that crosses the limit; refuses once already at or over it. |
track_only | Records spend and never refuses. |
A budget can also carry perRunCapUsd, an independent ceiling on a single run’s estimate, checked in every mode except track_only. A refused run returns 402 and is never created:
HTTP/1.1 402 Payment Required

{
  "code": "budget_exceeded",
  "reason": "hard_stop",
  "budgetId": "b7f1c0e2-...",
  "scope": "project",
  "enforcementMode": "hard_stop",
  "limitUsd": 50.0,
  "spendUsd": 49.92,
  "runEstimateUsd": 0.3,
  "remainingUsd": 0.08
}
The refusal is durably recorded even though no run exists, so refusals are auditable. Costs and budgets covers rollups and the refusal log.
End to end
One request, followed through every object above. The workflow is generate-coloring-page; the intake asks for a cartoon lion.
| Stage | What happens | What you can read |
|---|---|---|
| 1. Budget check | Before anything is created, the run estimate is evaluated against any workspace, project, or workflow budget. | 402 budget_exceeded if refused; nothing created |
| 2. Run created | The run is persisted with an id and pinned to workflow version 2026.09.16. | run-7c41e9a2, status pending |
| 3. step-1 render | The image model bound to imageGenerator renders the line art. One cost row is written. | ledger row, estimated → provider_reported |
| 4. step-2 post-process | A local tool thresholds the image, seals contour gaps, and raises strokes to the print floor. No provider call, no cost. | step record, $0 |
| 5. step-3 audit | A local tool measures stroke weight, grey, margin ink, and gaps. | qa.checks[line-art-audit] |
| 6. step-3b text gate | An llm step OCRs the page and returns a verdict. requireTrue: "pass" means a falsy verdict stops the run here. | qa.checks[text-gate] |
| 7. step-4 classify | An llm step produces catalog metadata from the declared category list. | metadata.classification |
| 8. Artifact | The output is persisted with its content, qa record, and metadata, and linked to the run. | artifact-0dc32dbb |
{
  "id": "run-7c41e9a2",
  "status": "completed",
  "artifactId": "artifact-0dc32dbb",
  "durationMs": 48213,
  "totalCosts": {
    "estimatedUsd": 0.0142,
    "actualUsd": 0.0142,
    "currency": "USD",
    "status": "provider_reported"
  }
}
Because this template declares no approval gate, the run went from running to completed without stopping. Had it declared one, the run would be sitting at review with the same artifact already stored, waiting for a decision.
Running the same intake again produces a different artifact — the model samples differently each time. These are three production runs of one prompt:


Each is its own artifact with its own id, cost rows, and quality record. This is why runs and artifacts are separate objects: the workflow is the constant, and each execution of it is independently stored and independently auditable.
Generate a clip-art asset walks a full run with live request and response bodies.
What Esy manages
Esy is responsible for executing workflows and preserving how their outputs were produced: provider routing, retries, quality checks, human review state, artifact storage, and cost capture.
It does not measure what happens to an artifact after it leaves — sales, clicks, engagement, or watch-through are the consuming product’s concern. It does not integrate with distribution marketplaces as a core responsibility. And it is not a chat API: a conversation can be an input to a workflow or be stored as an artifact, but the unit of work is a run, not a message.
- Workspace and project organize access and spend. Workflow, run, and artifact are the execution objects.
- A workflow declares
intakeSchema,runtimeSteps,gates,providers,budgetPolicy, andartifactSchema. Steps name roles;providersbinds roles to models. - Ten run statuses, six terminal. A run only stops at
reviewif its workflow declares anapprovalorhitlgate. - Steps execute; gates evaluate. Automated checks are
requireTrueon the step that produces the verdict; human checks are entries ingates. - Cost is one ledger row per provider call, in three states, enforced against budgets before the run is created.